One Block, Multiple Depths
Recurrent Vision Transformers with Depth-Programmed Experts
arXiv preprint, October 2026
Abstract
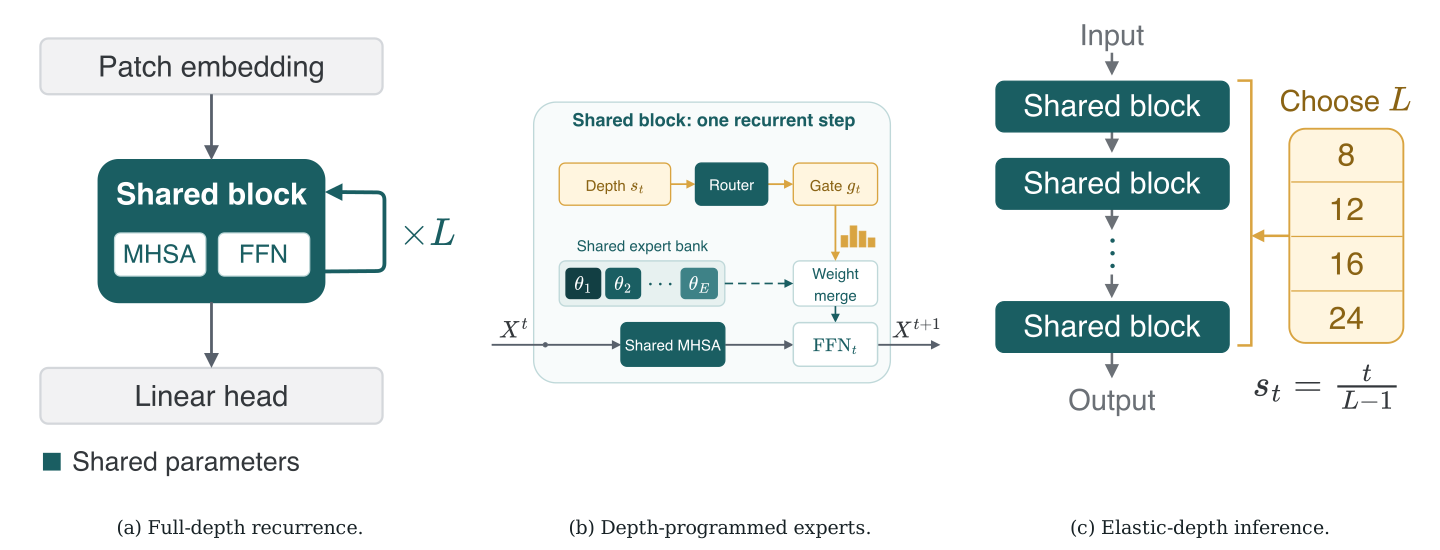
reViT explores whether a single recurrent Transformer block can replace a full-depth vision encoder while preserving accuracy at comparable inference FLOPs. It shares attention across recurrent steps and constructs each step's feed-forward network by mixing a small shared bank of experts in weight space. A continuous normalized-depth coordinate controls the mixture, allowing different transformations at different depths.
The paper evaluates supervised ImageNet-1k training and distillation from a DINOv2 teacher. A model with eight experts, trained using only the teacher's final output features, retains nearly all of the teacher's ImageNet linear-probe accuracy and transfers to classification, segmentation and depth prediction.
Elastic-depth training enables one checkpoint to run at multiple tested depths. For deployment at a fixed depth, the recurrent block can also be expanded into a conventional dense graph, removing online routing and weight merging while increasing deployment storage.
Key contributions
-
One recurrent Transformer block
Replace a stack of separate vision Transformer blocks with one shared block applied repeatedly.
-
Experts programmed by depth
Use a continuous normalized-depth coordinate to mix a small bank of feed-forward experts in weight space, retaining one feed-forward network evaluation per recurrent step.
-
Compact vision encoders
Trained from scratch on ImageNet-1k, reViT-B/16 matches DeiT III accuracy with about 70% fewer stored parameters at comparable inference FLOPs.
-
One checkpoint, multiple depths
Elastic-depth training lets a single checkpoint operate at multiple tested inference depths by resampling the same normalized-depth interval.
Citation
If you use this work, please cite:
@article{bulat2026one,
  title={One Block, Multiple Depths: Recurrent Vision Transformers with Depth-Programmed Experts},
  author={Bulat, Adrian and Ouali, Yassine and Tzimiropoulos, Georgios},
  journal={arXiv preprint arXiv:2610.12448},
  year={2026},
  eprint={2610.12448},
  archivePrefix={arXiv},
  primaryClass={cs.CV},
  url={https://arxiv.org/abs/2610.12448}
}